
What is token engineering?
Token engineering is the practice of measuring, optimizing, and governing AI token consumption to improve the value an organization gets from AI. In software development, it connects spending on AI coding tools and agents to the work they produce, including shipped features, resolved incidents, and completed customer requests.
Tokens have become a managed engineering resource, so teams need to evaluate how model choice, agent context, and execution policies affect both cost and software delivery outcomes. Faros CEO, Vitaly Gordon, describes this approach as a shift toward understanding what each investment in AI actually produces.
Why does token engineering matter?
A typical AI usage dashboard can show consumption and spending, but engineering leaders also need to understand whether that spending helped deliver useful, reliable software.
That requires connecting costs to what happens throughout development. An agent may generate a change quickly, but the work can still require extensive correction, review, or subsequent attempts. Those downstream costs affect the return on the original investment.
Faros’s Speed Trap research illustrates why this connection matters. Growing AI adoption can accelerate delivery while increasing pressure on review, QA, and production operations. Token engineering brings spending and delivery performance into the same conversation.
How does token engineering work?
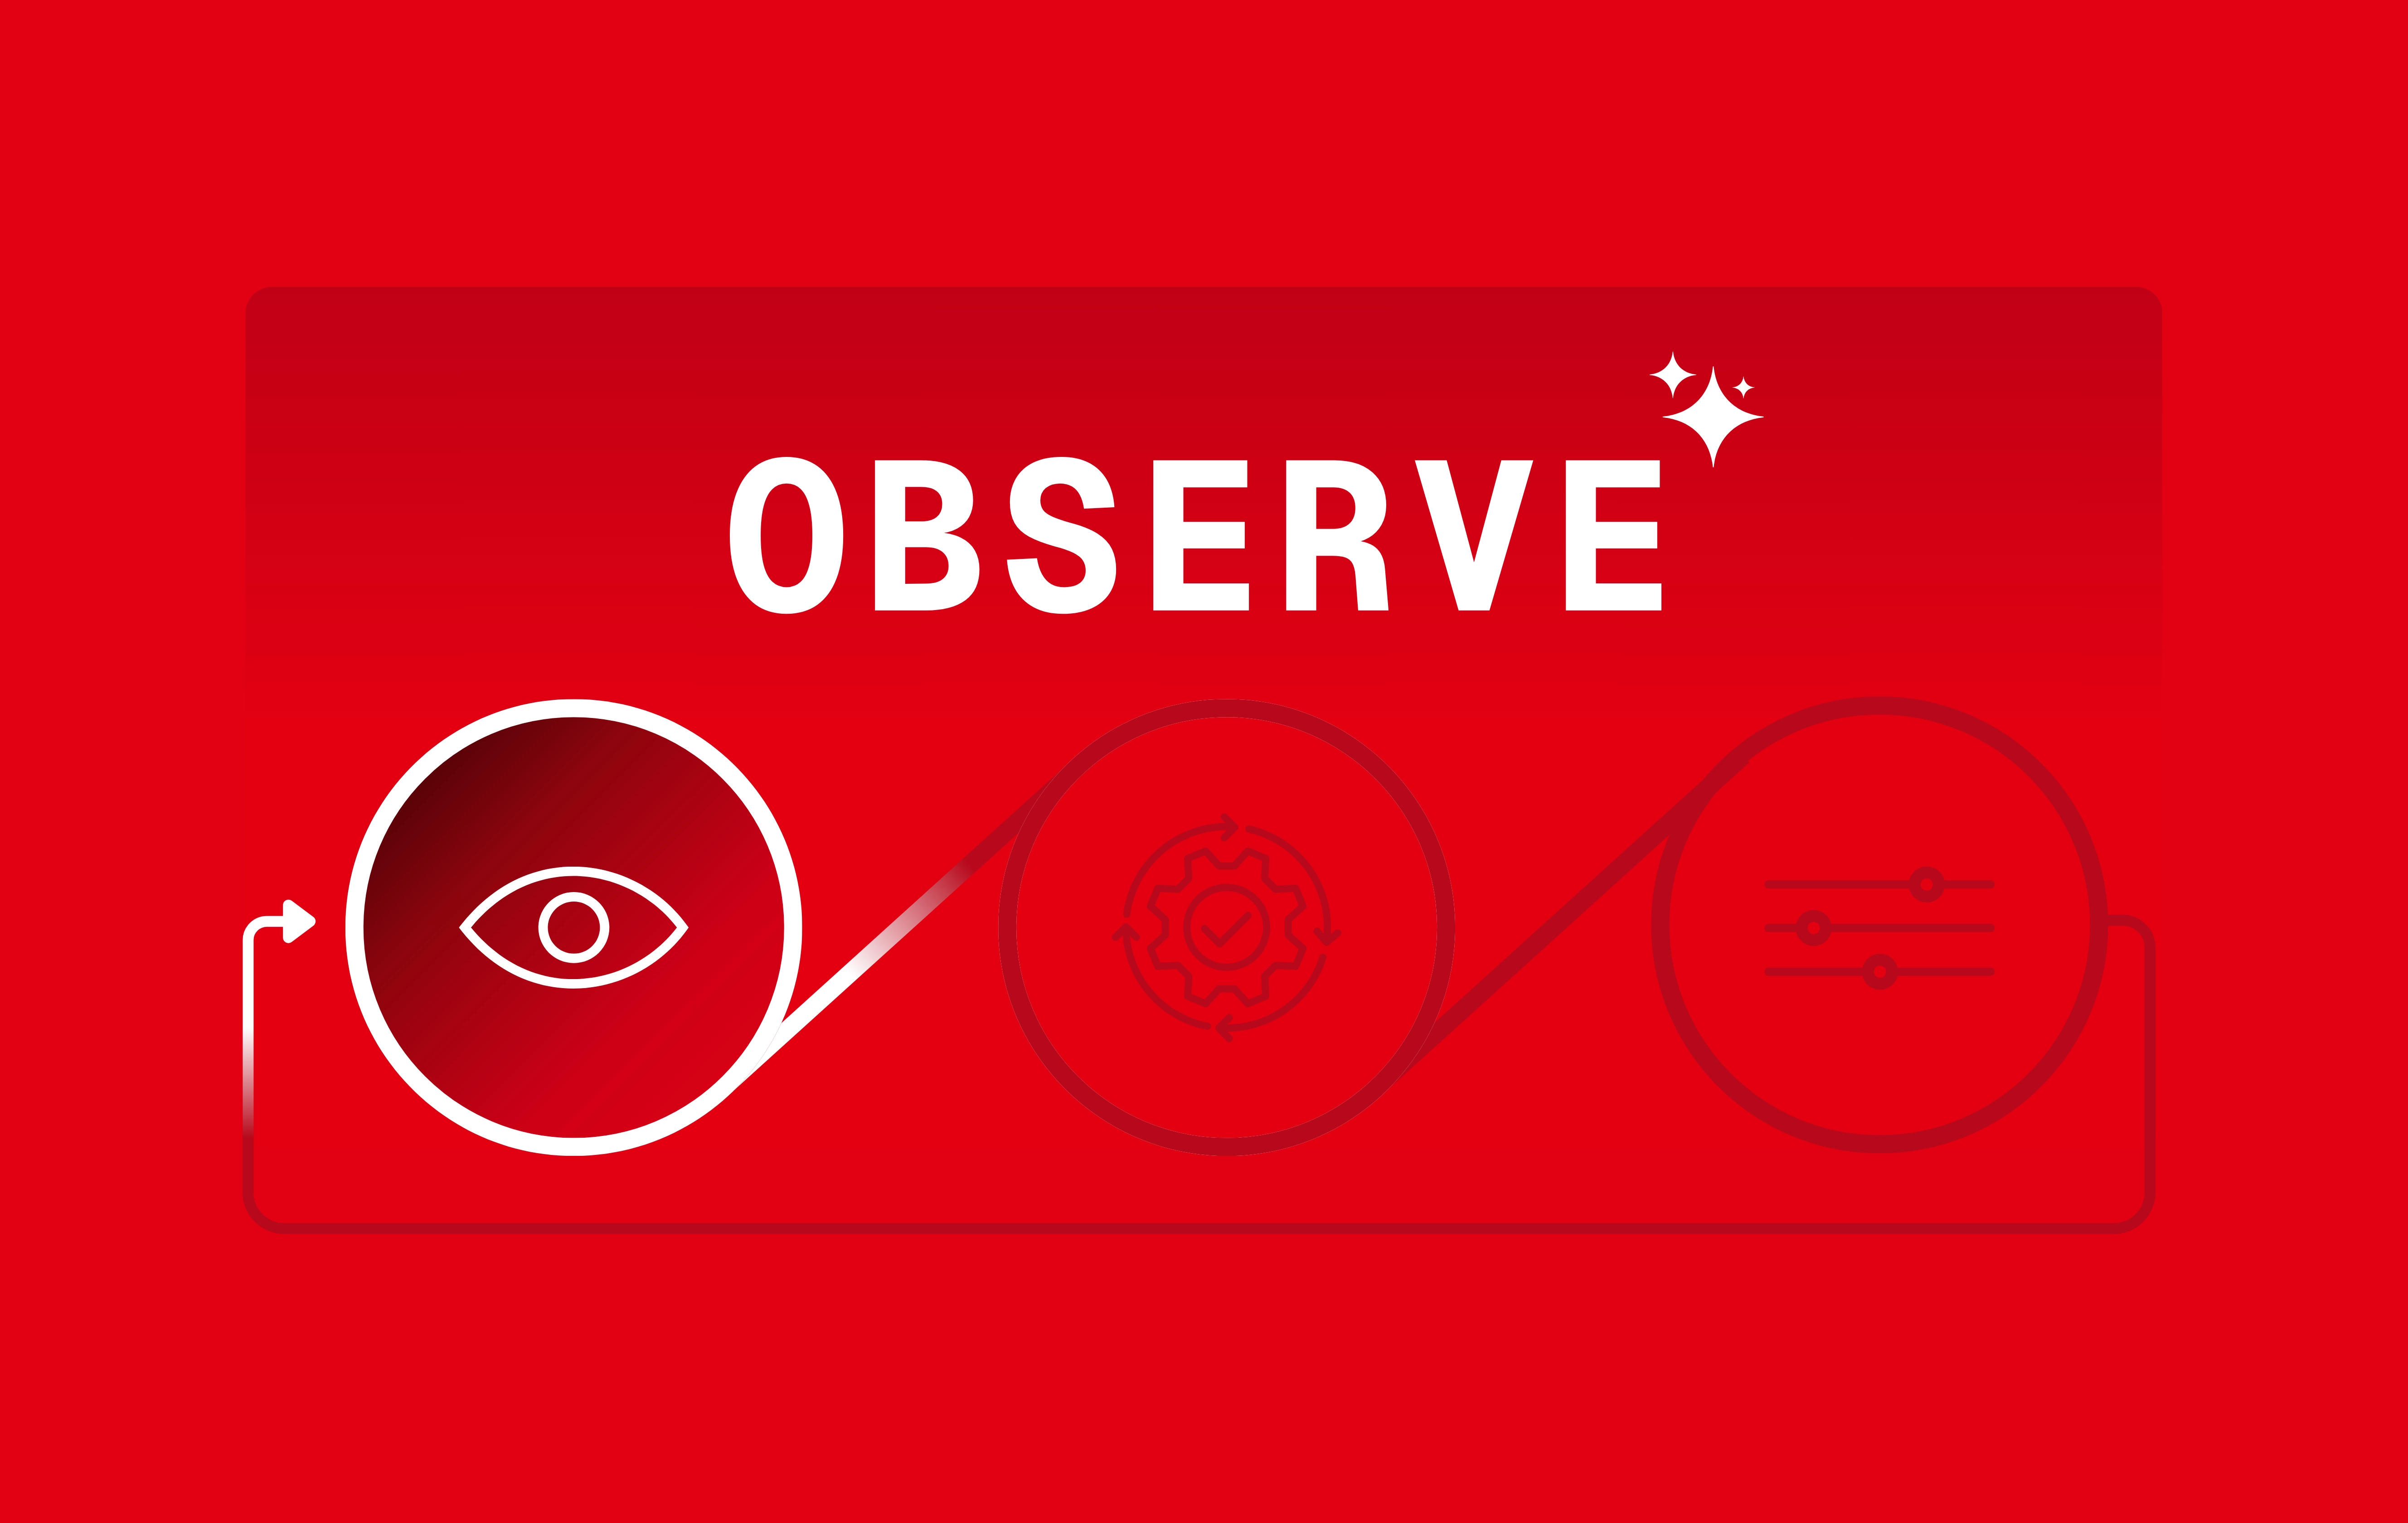
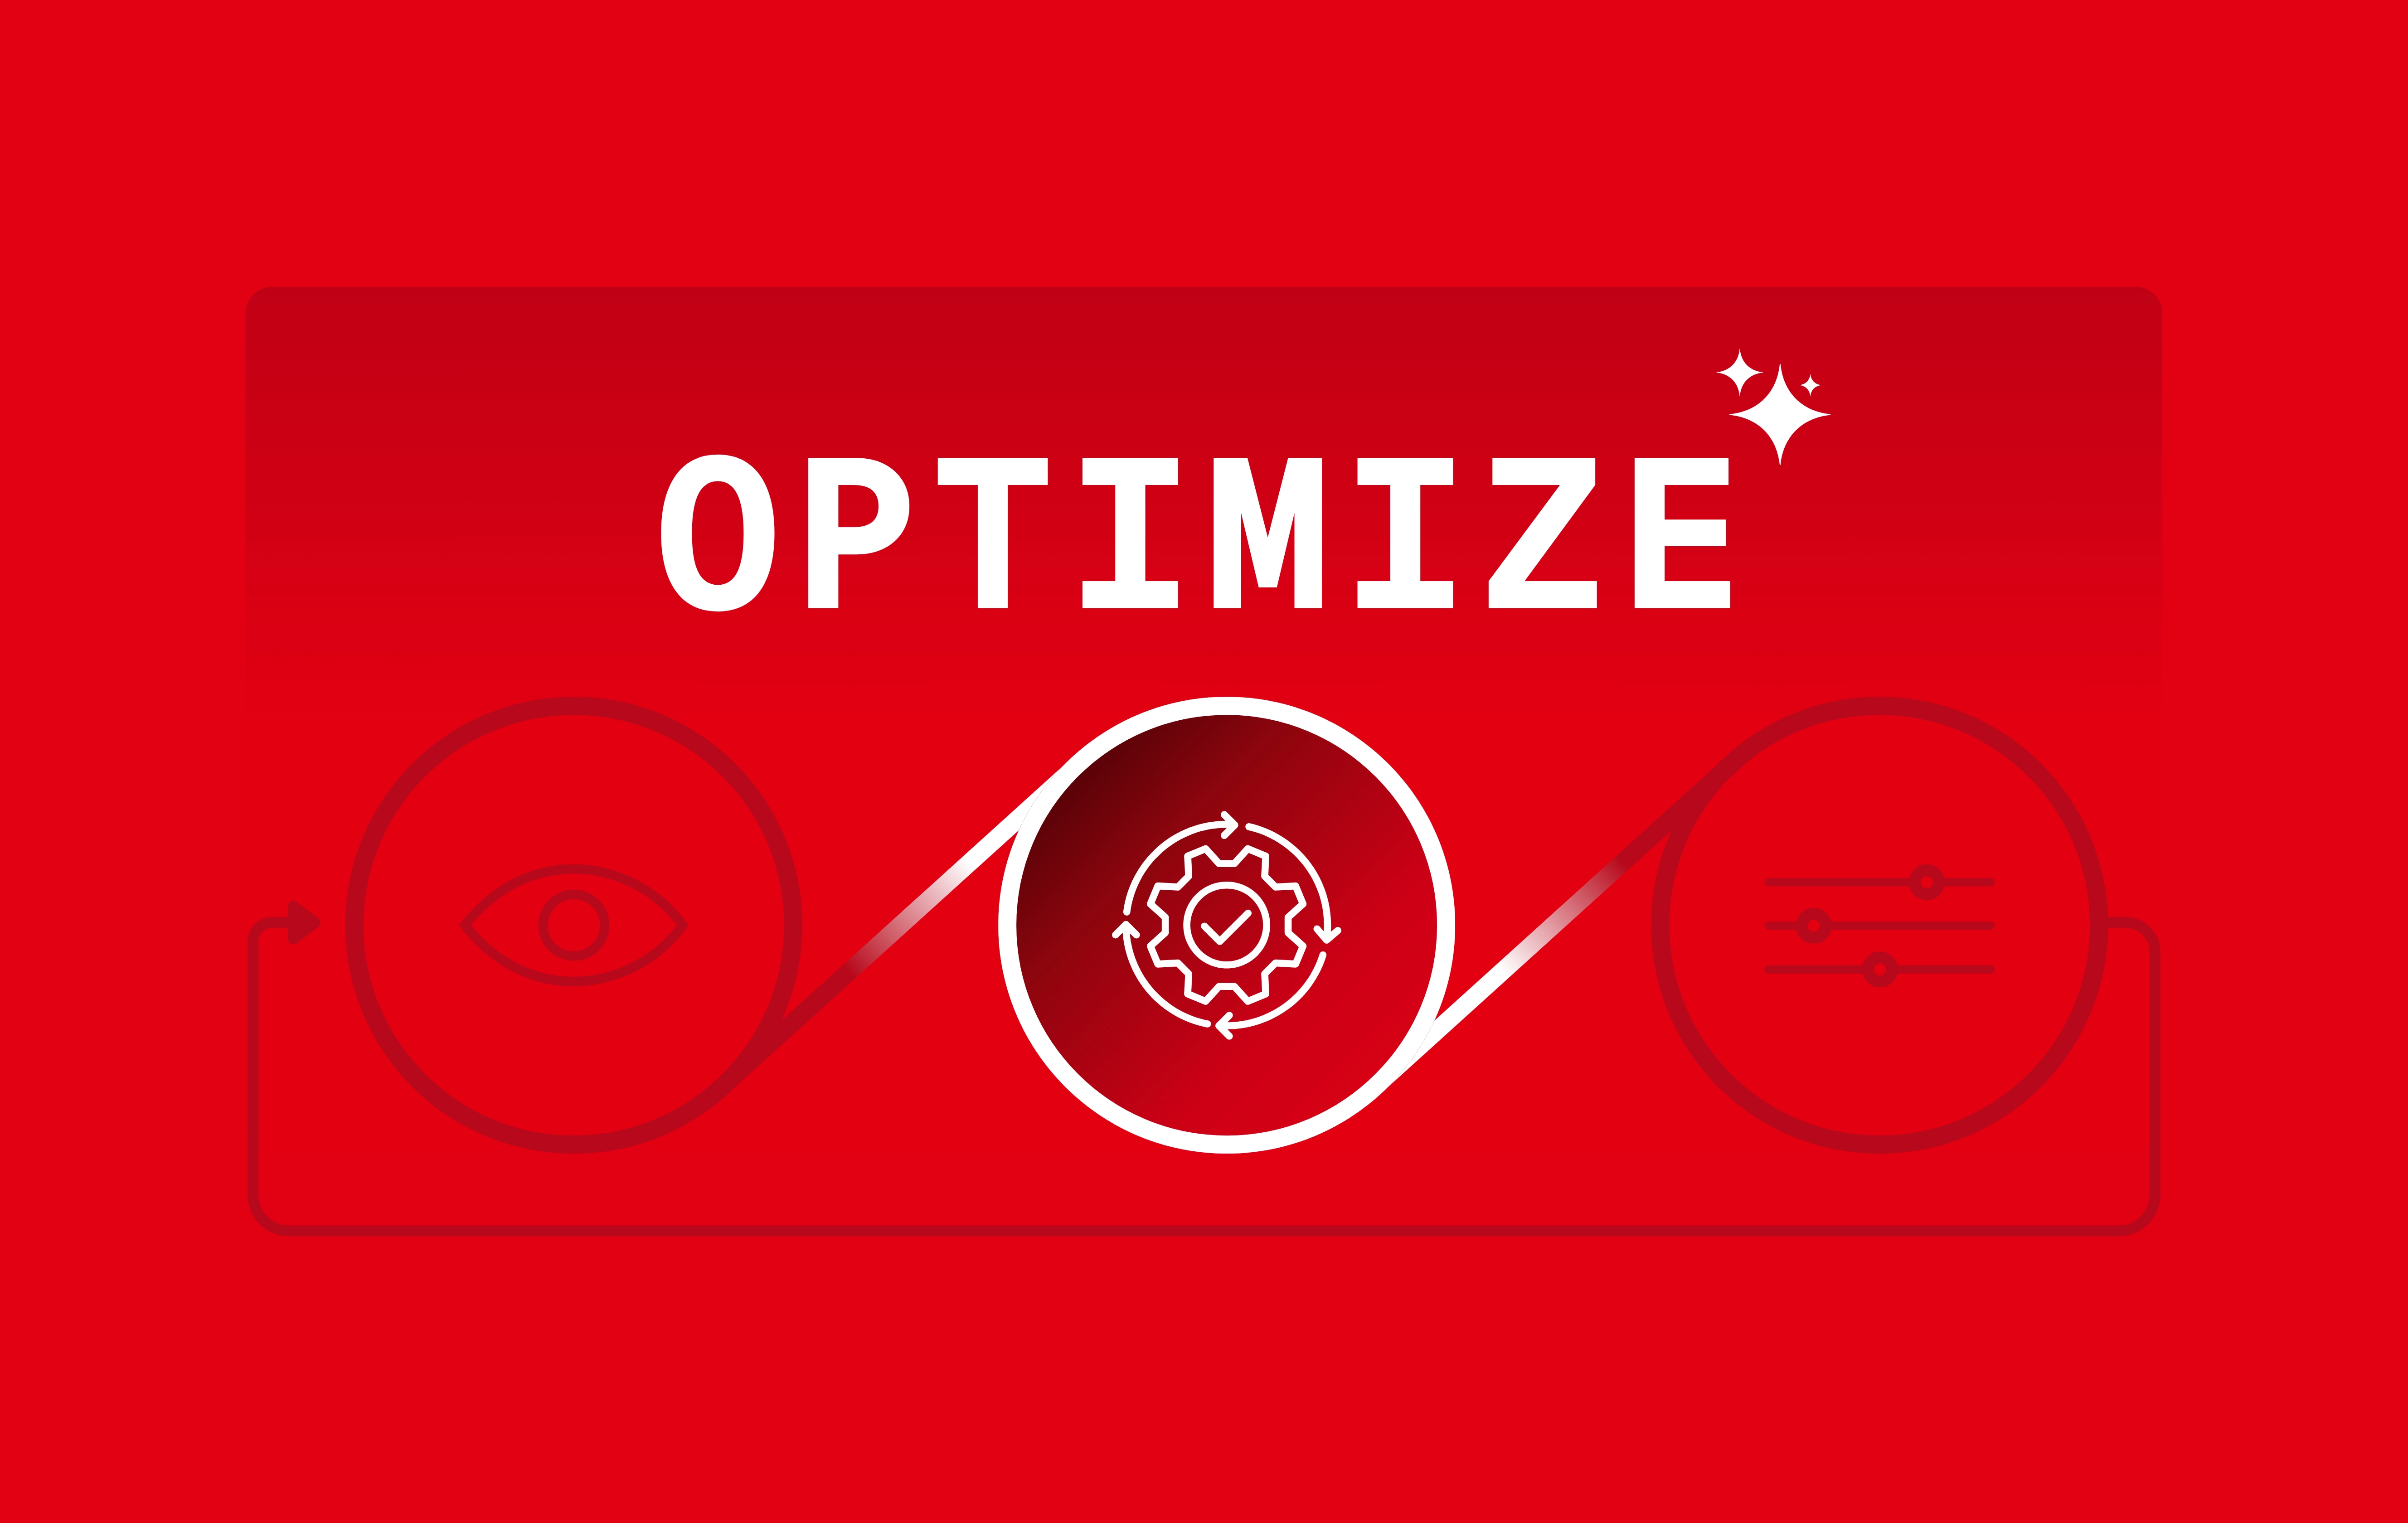
Token engineering operates through a continuous loop of Observe → Optimize → Govern. Each stage informs the next, connecting visibility into spending with improvements in how AI coding work gets done.
Observe AI spending and outcomes
Observability into AI spend connects token consumption to the people, agents, teams, and projects behind it—and to the work that spending produces. Leaders can see which activities drive costs, how spending compares with budgets, and whether increased consumption translates into completed work.
AI coding cost allocation makes this information useful across engineering and finance. Breaking down spending by team, tool, model, repository, and workload supports chargebacks, budget decisions, and forecasting. Connecting those costs to delivery outcomes helps teams investigate where AI investment is paying off and where work requires repeated correction.
Optimize model routing and agent context
Optimization improves both which model performs a task and what information it receives.
Model routing matches tasks to model and agent-harness combinations based on evidence from an organization’s own engineering work. Evaluating routes against historical tasks helps teams balance cost, speed, and quality for their codebase. A lower-cost route may handle routine work effectively, while a more capable model may justify its price on complex tasks.
Context engineering strengthens those routes by supplying relevant architectural decisions, codebase standards, system history, and testing requirements. Feeding review findings back into that context helps address recurring mistakes. Together, routing and context improvements aim to reduce the cost of producing work that meets requirements.
Govern AI usage and execution
Governance turns budget, model, and tool decisions into enforceable policies. Teams define approved models, harnesses, and configurations, then apply those rules where AI requests occur.
AI coding governance also establishes quotas by team, project, or business unit, with defined responses as limits approach. Lower-priority work might move to a cheaper model, be throttled, or require approval. Session records preserve which model ran, which policy applied, and what the work cost.
These controls make approved practices repeatable and auditable. Observing their effect on spending and outcomes starts the loop again, giving teams evidence for their next improvement.
What does token engineering look like in practice?
Consider a hypothetical wherein a team is evaluating two ways to automate a maintenance task. One setup costs $2 per attempt and succeeds once in four attempts. Another costs $5 per attempt and succeeds once in two attempts.
Across four attempts, the first spends $8 for one successful result. The second spends $10 for one successful result across two attempts. The first appears more economical on that measure.
Suppose correcting each failed attempt takes an engineer 20 minutes. The first setup requires 60 minutes of correction across those attempts; the second requires 20. The team must weigh token spending alongside the human work required.
Now imagine these decisions across hundreds or thousands of engineers using AI coding tools, with autonomous agents working throughout the software development lifecycle. Model choices, token spending, and the need for corrections compound across the organization. Token engineering gives leaders the visibility and control to improve how that work gets done, directing AI investment toward better engineering outcomes.
How can teams get started with token engineering?
See where your AI coding spend goes, which model routes and context deliver the best results, and how to enforce policies across your organization. Get a Faros demo to see how token engineering connects your AI investment to measurable engineering outcomes.