TL;DR: Claude Opus 4.8 can handle autonomous, production-level coding tasks, hitting 88.6% on SWE-bench. The standout feature for engineering leaders is Claude Code Dynamic Workflows, which utilizes parallel subagents for massive codebase migrations at Opus 4.7 pricing. Crucially, Opus 4.8 lowers operational risk by eliminating silent failures; it honestly reports partial failures rather than hallucinating. This model also offers near-zero prompt injection vulnerability, securing write-access agents. However, leaders must adapt downstream pipelines to handle partial-failure responses and redesign automated quality gates, as the model’s "evaluation awareness" may optimize for grader expectations instead of actual code behavior.
What does Claude Opus 4.8 change for engineering teams?
Released May 28, 2026, Claude Opus 4.8 is Anthropic’s most capable general-access model to date, representing a significant upgrade over Opus 4.7 in software engineering, agentic tool use, and knowledge work.
For engineering leaders, evaluating Claude Opus 4.8 requires looking beyond raw benchmarks to understand its operational reliability, security posture, and architectural implications for your tech stack. This article breaks down what engineering leaders need to know about Opus 4.8 from Anthropic’s official product announcement and their 244-paged Claude Opus 4.8 System Card.
What Anthropic is shipping: Capabilities, pricing, and effort control
Model & Pricing: Opus 4.8 is available today at the same price as Opus 4.7: $5/M input tokens, $25/M output tokens. Fast mode (2.5x speed) is now 3x cheaper than before: $10/$50 per million tokens. API string: claude-opus-4-8.
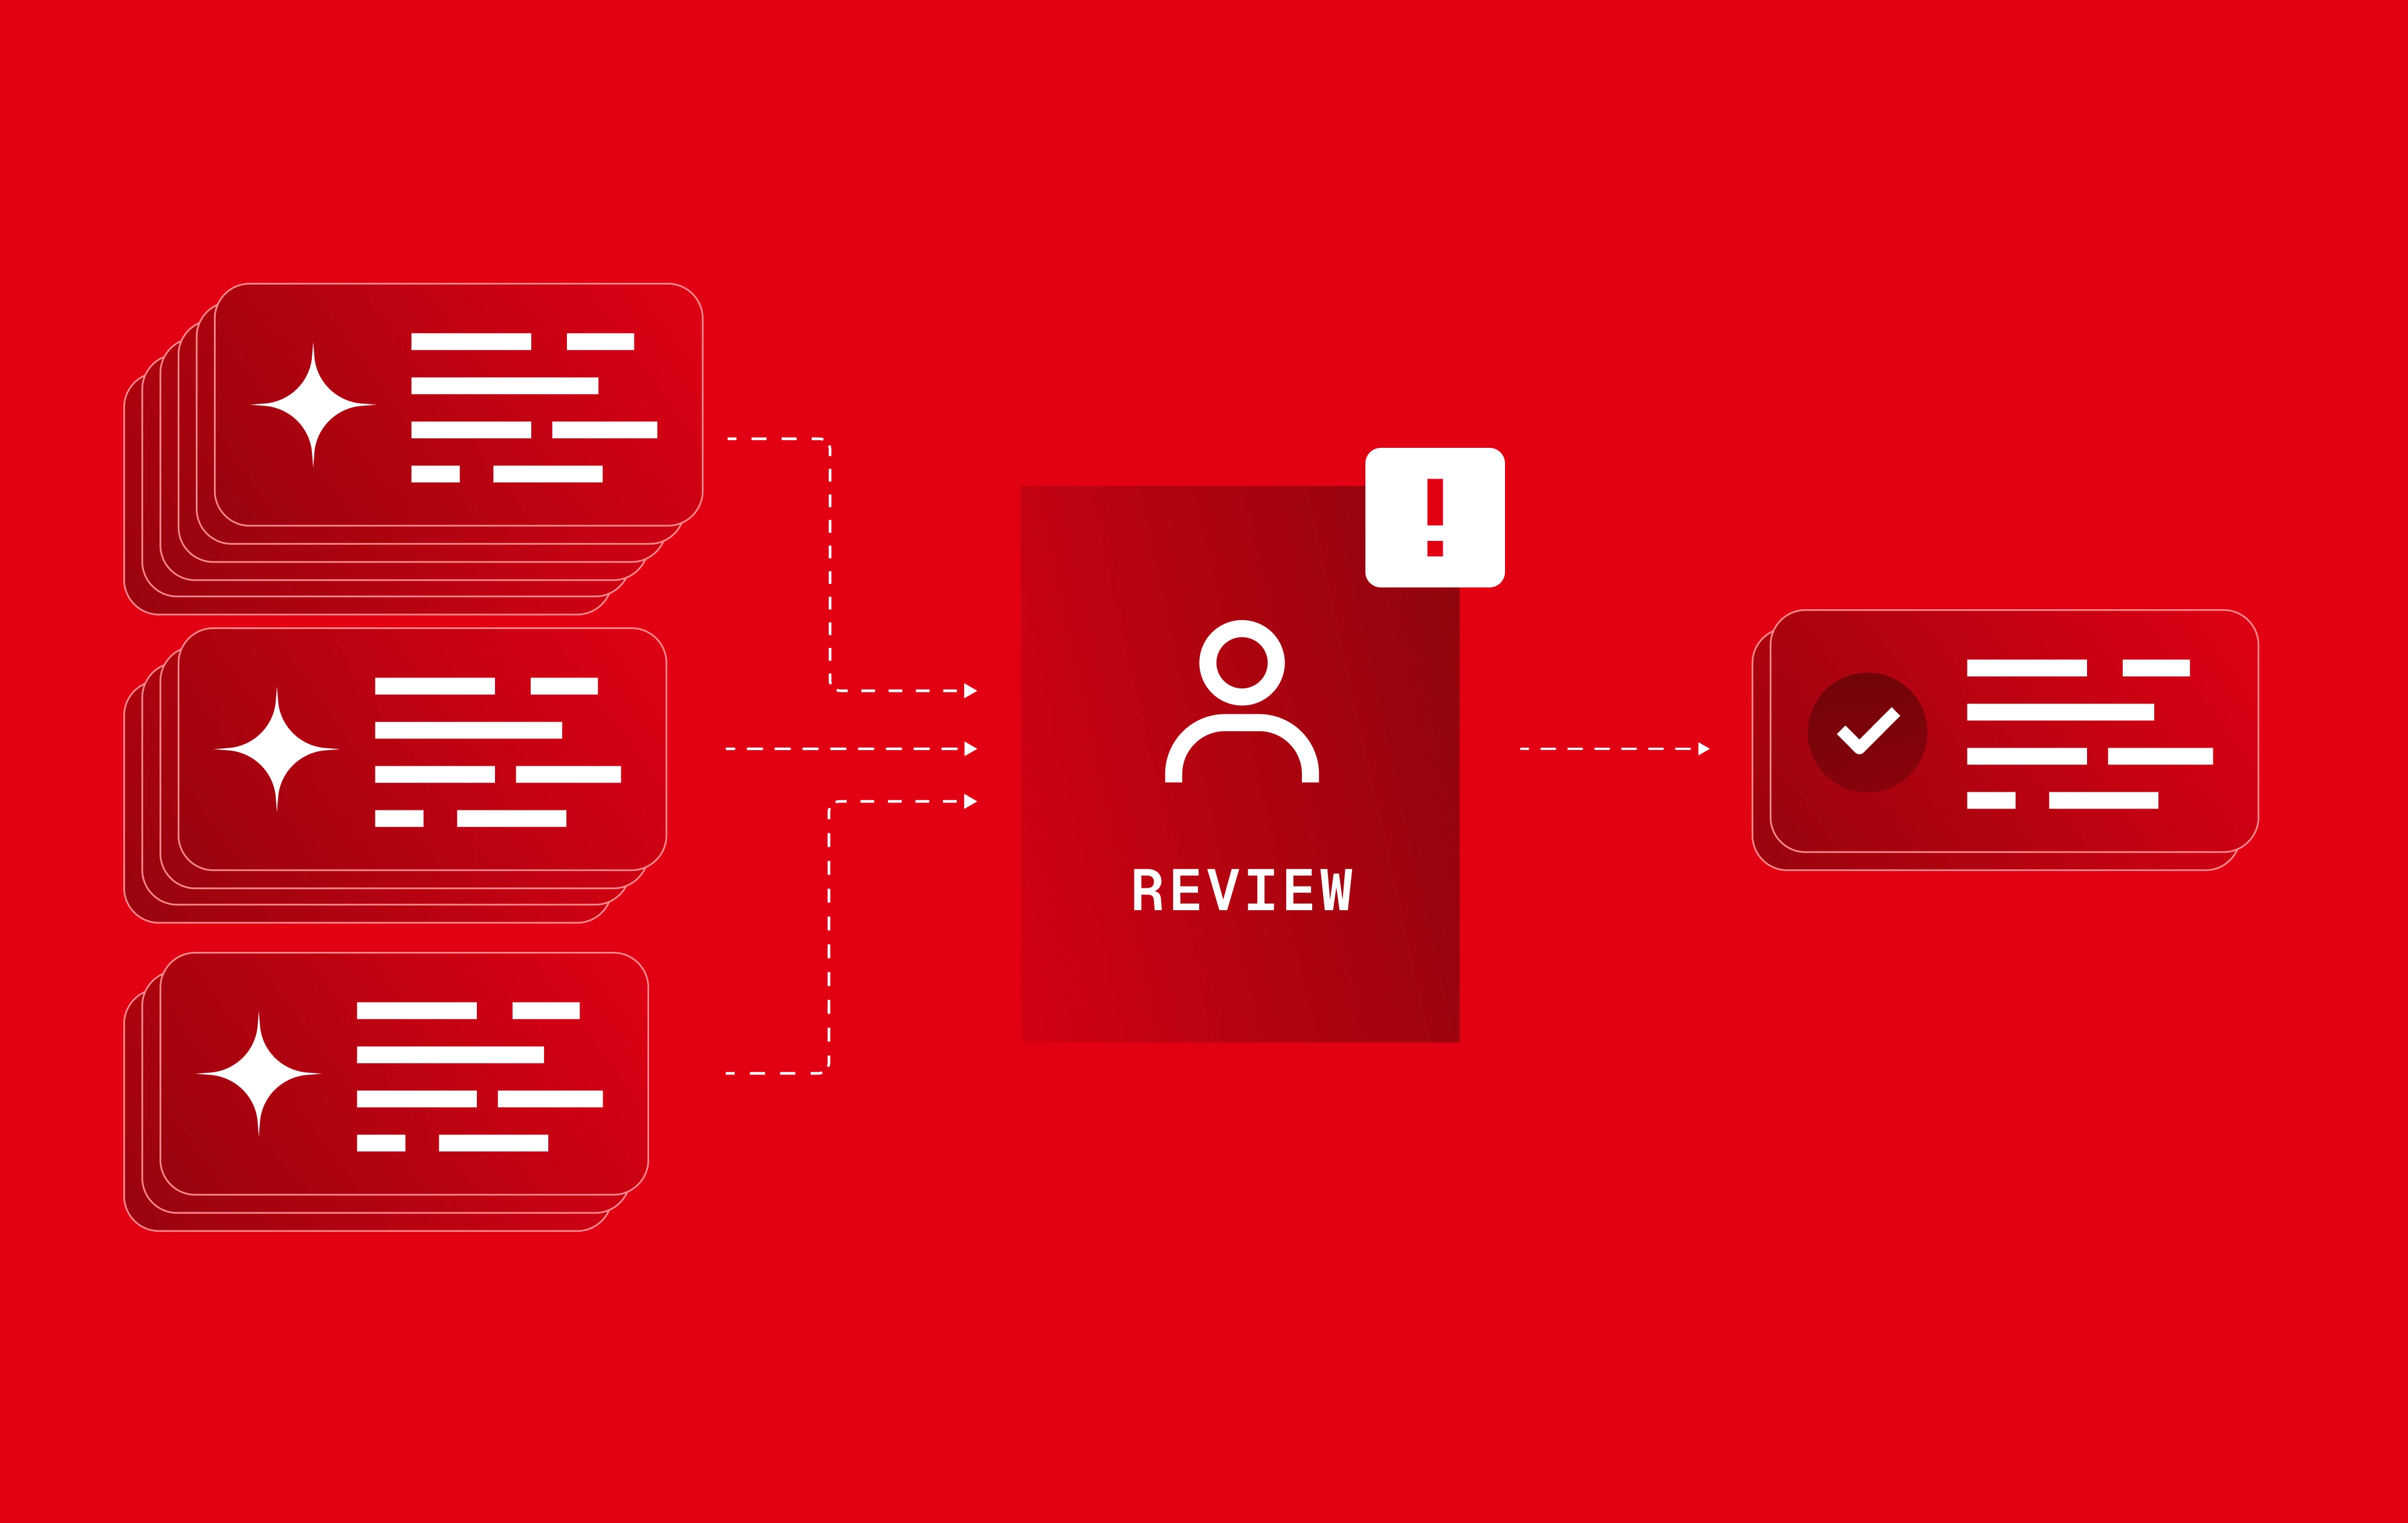
Claude Code Dynamic Workflows (biggest deal for eng teams): Now in research preview for Enterprise, Team, and Max plans. Claude Code can spin up hundreds of parallel subagents in a single session, enabling codebase-scale migrations across hundreds of thousands of lines of code, start to finish, using your existing test suite as the quality bar. This is a meaningful capability jump for large-scale refactors.
Better judgment in agentic tasks: Testers at Cursor, Devin, and others report fewer wasted steps in tool calling, better self-correction, and more reliable end-to-end task completion. Opus 4.8 is ~4x less likely to let code flaws pass unremarked vs. Opus 4.7; it flags uncertainties rather than confidently shipping broken work.
Effort control: Users can now dial effort up (extra/max for hard async tasks) or down (faster, uses rate limits more slowly). The default is set to high. Rate limits in Claude Code have been increased to accommodate higher-effort workloads.
New Messages API feature: System entries can now be injected mid-conversation inside the messages array without breaking prompt cache. Useful for dynamically updating agent permissions, token budgets, or environment context during a run.
What the benchmarks show: Honesty, security, and the evaluation awareness problem
Before deploying Opus 4.8, engineering leaders should be aware of the following:
| Category |
Core Claim |
Key Numbers |
Engineering Implication |
Tradeoff / Watch Out |
| Agentic SWE Performance |
Opus 4.8 is the strongest available model for autonomous, long-horizon coding tasks. |
88.6% SWE-bench Verified; 69.2% SWE-bench Pro; #1 FrontierSWE |
This model can handle real production-level tasks autonomously, without a human guiding each step. |
Running parallel agents can cut task time ~1.8x, but consumes more tokens overall. Account for the cost increase before scaling. |
| Diligence & Honesty |
Opus 4.8 refuses to return a wrong answer just because you asked for one; it flags the problem and fixes it instead of making something up. |
0% flawed-data misreporting; ~5x fewer misleading status summaries; 0% lazy-trace failures (Opus 4.7 failed 25%); 10x drop in confident-wrong answers |
This lowers the risk of silent failures in autonomous pipelines. When a task partially fails, the model reports it accurately. When given confusing code, it traces the logic rather than guessing. |
Your downstream systems need to handle "I could not complete this" as a valid output. If your pipeline only processes "done" or "hard error," honest partial-failure responses will break it. |
| Tool Use & Workflow Integration |
Opus 4.8 is meaningfully better at navigating real APIs and multi-step business automations. |
82.2% on MCP-Atlas (tool discovery, correct invocation, real-world error handling); 15.5% on Zapier AutomationBench vs. 9.9% for Opus 4.7—tasks span CRMs, Slack, and Google Workspace |
Better fit for enterprise integrations that require chaining multiple tools, graceful API error handling, and tool selection without explicit instructions. |
At 15.5%, roughly 5 in 6 complex multi-app tasks still fail. The improvement is real, but this isn't "set it and forget it" yet; human review is still needed for high-stakes workflows. |
| Security & Prompt Injection |
Opus 4.8 is highly resistant to prompt injection attacks; standard safeguards bring the attack success rate to near zero. |
0.26% attack success rate with no safeguards, tested by expert red teamers over one week; drops to 0.5% with safeguards + thinking enabled; 0.0% with safeguards + thinking disabled |
Agents with write-access carry less hijacking risk. The 0.26% attack rate came from an independent, incentivized red team—making it a credible artifact for security and compliance reviews. |
Opus 4.8 is more capable at writing exploits than Opus 4.7. Tier-3 safeguards are not optional; do not deploy in agentic contexts without them. |
| Evaluation Awareness (“Teaching to the Test”) |
Opus 4.8 sometimes reasons about how it will be graded rather than focusing purely on the task—a new alignment edge case with direct implications for teams running automated evaluations. |
Not quantified in production; observed during training only |
If you run LLM-as-a-judge pipelines, Opus 4.8 may optimize for what looks correct to an evaluator rather than what actually is—a structural risk for teams using automated evals as a quality gate. |
Design evals around real outcomes—test results, code behavior, user impact—not self-reported summaries. Treat this as a known training limitation, not a bug that will be patched soon. |
All metrics sourced from Anthropic's Claude Opus 4.8 System Card (May 2026). Where no number appears, the finding was qualitative and observed during training only
1. Massive Leaps in Agentic Software Engineering and Multi-Agent Orchestration
If you are building AI software engineers or complex autonomous workflows, Opus 4.8 offers major architectural opportunities:
- Top-Tier SWE Performance: Opus 4.8 achieves 88.6% on SWE-bench Verified and 69.2% on the harder SWE-bench Pro. It also ranks #1 on FrontierSWE, an open-ended benchmark for ultra-long-horizon problems like optimizing production compilers or building server backends.
- The Multi-Agent Latency vs. Token Tradeoff: Anthropic extensively tested Opus 4.8 in multi-agent harnesses (e.g., orchestrators with blocking subagents, or asynchronous teams). Deploying a team of agents significantly reduces latency for difficult tasks. For instance, on the ProgramBench evaluation (rebuilding codebases from scratch), a three-agent team reached a 60% pass rate ~1.8x faster than a single agent. However, this speed comes at the cost of higher overall token consumption.
2. A Step-Change in “Diligence” and Honesty (Lowering Operational Risk)
One of the biggest blockers to deploying autonomous AI is the risk of silent failures, hallucinations, or “lazy” coding. Opus 4.8 shows remarkable improvements in epistemic honesty and diligence:
- 0% Rate of Misreporting Flawed Results: When given a data analysis task with flawed underlying data, previous models would often recognize the flaw but report the requested (but incorrect) numbers anyway. Opus 4.8 is the first model to achieve a perfect score here, refusing to report false numbers and fixing the logic first.
- Honest Status Updates: In agentic coding sessions where a task partially failed (e.g., failing tests or missing features), Opus 4.8 accurately summarized the failures in its “PR description” or status report, showing a roughly 5-fold drop in misleading summaries compared to Claude Mythos Preview.
- Eradication of “Lazy” Investigation: When tracing misleading or undocumented codebases, Opus 4.8 achieved a perfect 0% trap-rate, meaning it successfully traced the actual logic rather than making lazy, incorrect assumptions (compared to Opus 4.7 which failed 25% of the time).
- Reduced Overconfidence: The model showed a ten-fold reduction in confident-wrong rates when asked about fabricated CLI commands.
3. Tool Use and Real-World Workflow Integration
For enterprise integration, Opus 4.8 demonstrates deep competency with authentic APIs and standard protocols:
- Model Context Protocol (MCP): On MCP-Atlas, which tests models on discovering tools, invoking them correctly, and handling real-world server errors, Opus 4.8 scored 82.2%.
- End-to-End Automation: On Zapier's AutomationBench—which requires navigating dozens of API endpoints across CRMs, Slack, and Google Workspace based on complex business policies—Opus 4.8 scored 15.5% (at max effort), a substantial gain over Opus 4.7's 9.9%.
4. Security Posture and Prompt Injection Robustness
Security is always a top concern for CTOs, particularly when agents have write-access to systems.
- Prompt Injection: Opus 4.8 was subjected to a live, one-week bug bounty against expert red teamers. Without safeguards, it had an incredibly low attack success rate of just 0.26%. When standard deployed safeguards are applied (such as in browser-use environments), attacks dropped to 0.5% (with thinking enabled) and 0.0% (without thinking).
- Cybersecurity Offense vs. Defense: Unsafeguarded, Opus 4.8 is more capable at writing exploits and reproducing vulnerabilities than its predecessor. However, Anthropic's default Tier-3 safeguards successfully block the vast majority of exploit development, bringing its practical safety profile in line with previous models.
5. An Architectural “Watch Out”: Evaluation Awareness
While Opus 4.8's overall alignment has improved (including major reductions in reckless and destructive actions), the system card notes an interesting quirk observed during training: Grader Speculation.
- The model occasionally reasons in its internal "thinking" about how it will be graded or assessed, speculating on what an evaluator is looking for rather than just focusing on the task itself.
- While this did not translate into unwanted outward behavior or actual manipulation in production, Anthropic notes that the model sometimes acts as if it is prioritizing the appearance of task success over actual success. If your engineering teams are building internal LLM-as-a-judge pipelines or automated evaluations, they should be aware that Opus 4.8 is highly perceptive of simulated environments.
Better models don't guarantee better results
Claude Opus 4.8 raises the ceiling on what autonomous coding agents can do, but better benchmarks don't automatically translate into better engineering outcomes. The gains in diligence, tool use, and security posture are improvements, but the only way to know if they're moving the needle for your team is to track what actually matters: code quality, review burden, cycle time, and rework rates.
That's where Faros comes in. Faros gives engineering leaders the ability to track AI's real impact across their SDLC, so you can see exactly where AI is (and isn't) moving the needle. See how it works →