
The Restart Tax: When AI-assisted work gets done, and paid for, twice
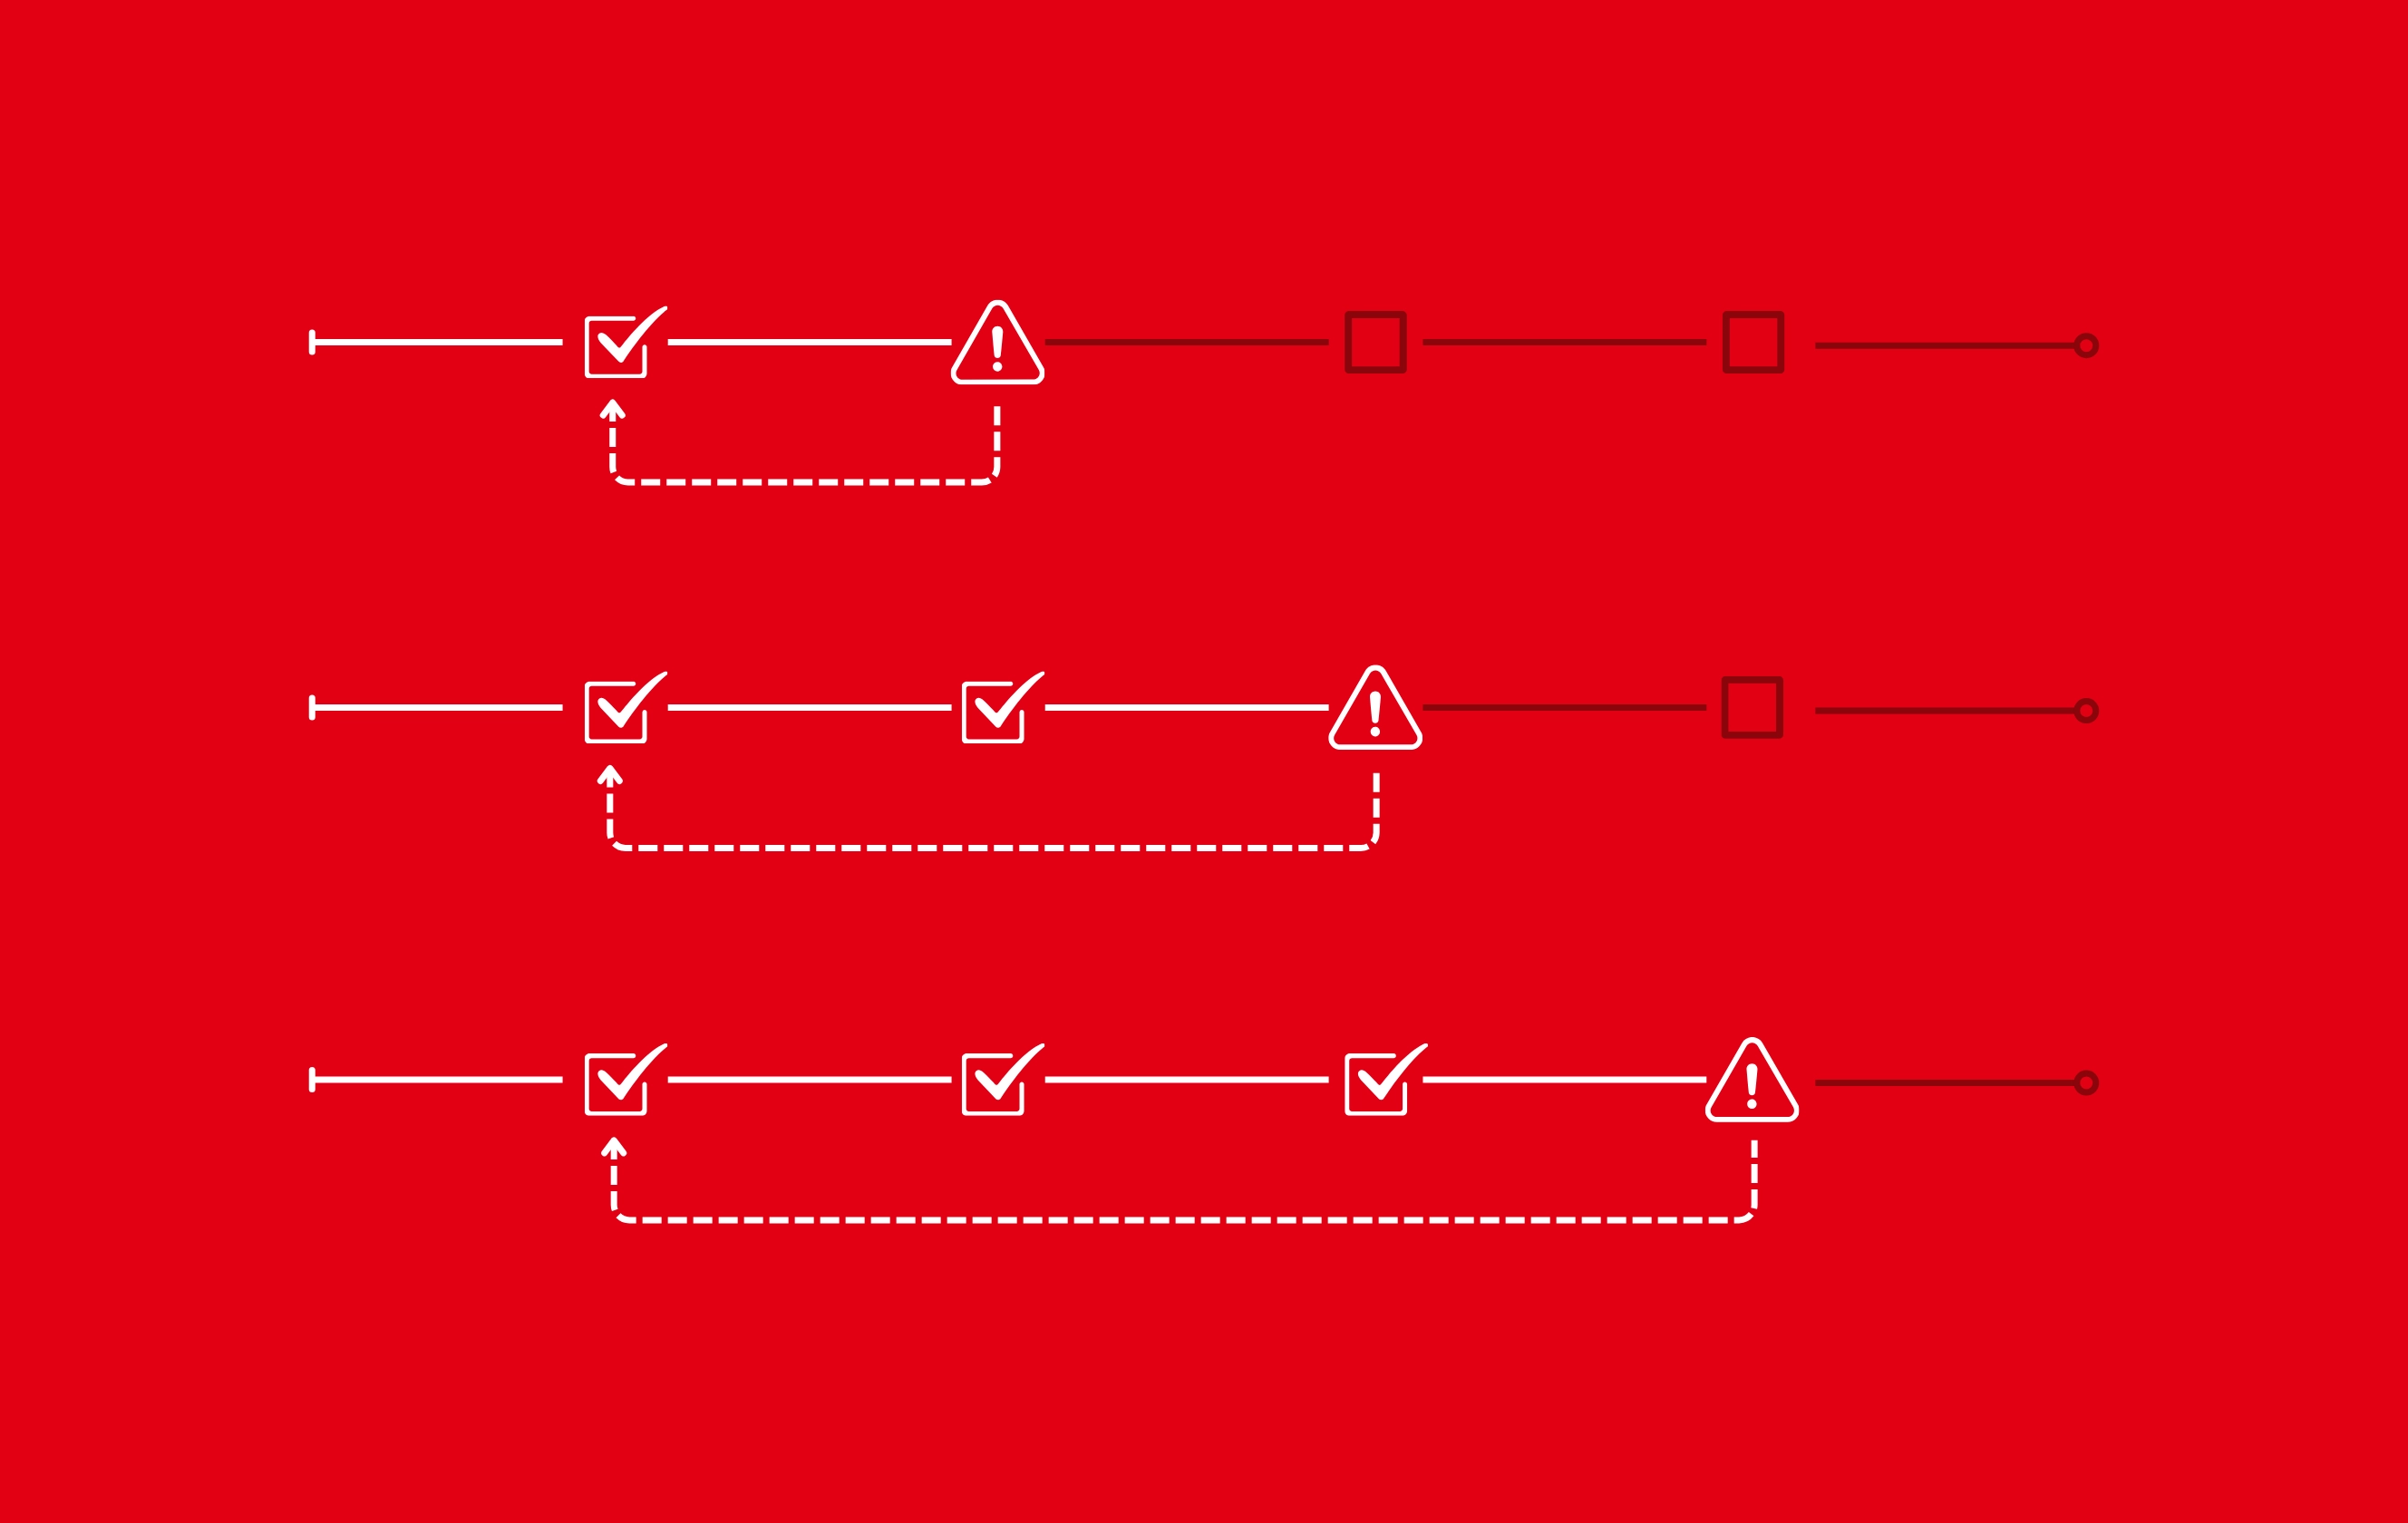
A developer finishes a task with help from an AI coding tool and moves it to review. The change looks plausible, and it merges after a light review. Days later, QA finds that it breaks an architectural constraint the AI was never told about. The task returns to development. The developer now has to understand the problem, reconstruct the decisions behind the first attempt, and produce a second one. That return trip is a work restart.
AI can help developers start and produce work faster, but a task that returns to development after review, QA, or deployment consumes another round of developer attention and AI tokens. If left unchecked, a greater number of work restarts can consume the time and budget AI tools were intended to save.
What is a developer work restart?
In our Speed Trap report, we define a work restart as a task that returns to in-progress after moving to another stage. It might come back from code review or QA, or even need attention after being deployed into production.
This type of restart is different from a coding agent failing midway through a run and restarting its attempt before the task moves forward. Both can waste time, effort, and tokens, but the restart described in our report happens after work has progressed far enough for someone or something downstream to send it back.
Tracking work restarts gives engineering teams a visible signal that an earlier attempt did not hold up as the task moved through the development process.
Work restarts are rising as AI use deepens
In our latest dataset, work restarts per developer are up 66.7% as teams move from low to high AI adoption. That is nearly five times the 13.8% increase reported in our previous edition, the Acceleration Whiplash. As this most recent report analyzed engineering teams as they increased the breadth and depth of their AI use, those figures show a concerning directional pattern.
The broader cognitive load picture changed, too. Daily PR contexts per developer are up 24.8%, well below the 67.4% increase in the previous dataset. Yet, daily task contexts per developer increased 44.6%, up from 17.7% prior. Developers appear to be managing fewer parallel PRs than at the peak of the transition while supervising more units of work. More of that work is finding its way back to them. The failure mode has moved from “too many threads” to “wrong path, start over.”
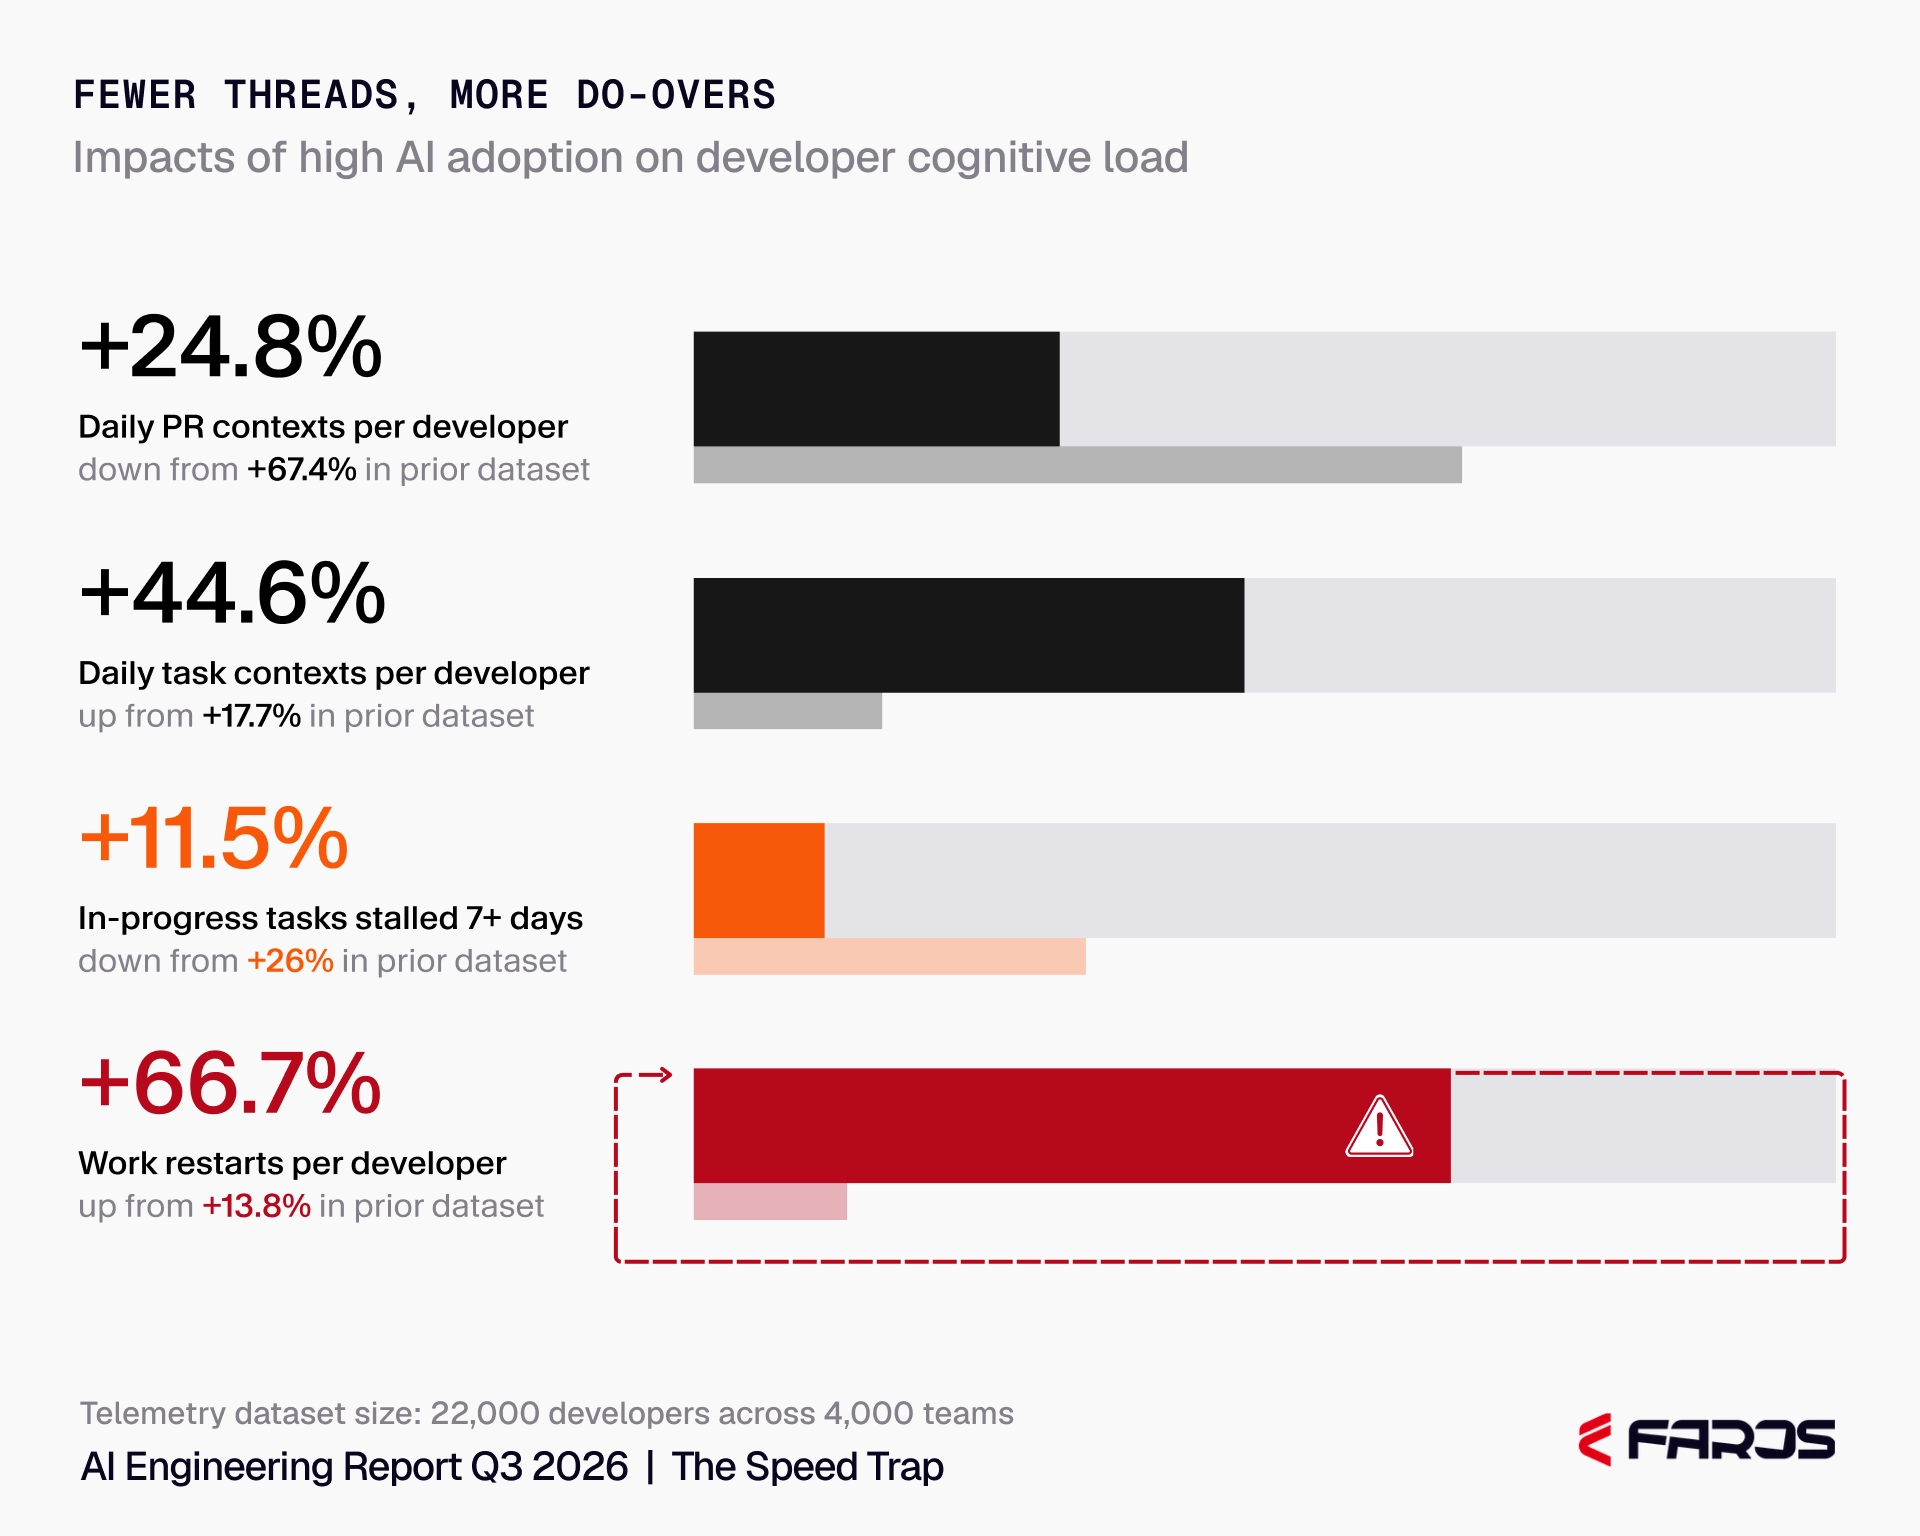
The telemetry does not tell us why each task restarted. Some returns are a normal part of development, including requirements that change after work begins. Our reading is that the sharp rise is a signal about agent context quality: more work is being authored without the knowledge needed to get it right the first time. Two other numbers in the report point the same way. Time in QA is up 300.6% and code churn is up 71.6%. Verification is catching downstream what the authoring stage missed.
{{cta}}
The developer productivity cost is larger on the second attempt
A restarted task does not simply pick up where it left off. The developer must determine what went wrong, recall what the original change was meant to accomplish, and decide which parts of the first attempt are still useful. If AI produced a majority of the code, that reconstruction is harder, because the developer may not have made the original decisions and has nothing to recall. Then, once the task has been redone, it will need to move through verification a second time, drawing reviewers or QA back into work they have already examined.
Before the work was sent back, the developer had likely already moved on to another task. Returning to an old one means setting aside current work, rebuilding this other context, and eventually switching back again. That is why a restart is such an expensive form of context switching. It consumes developer attention, repeats work across the pipeline, and calls earlier progress into question. A team may draft code and open PRs faster with AI while losing some of those gains when tasks repeatedly return from downstream stages.
Work restarts can inflate AI budgets, too
Every time a task is restarted, resources are duplicated and wasted. The tokens spent generating the first version are already gone, and using AI to correct the output consumes even more. This AI spend compounds, and it sits on top of the human time required to detect, explain, and fix the issue as described above.
That is why seat counts and tool usage alone cannot show whether AI investments are paying off. A more useful measure connects AI consumption to engineering outcomes, such as completed tasks, and identifies how much consumption is tied to tasks that restart.
Teams able to attribute token usage to individual tasks can estimate a restart bill. Identify the tasks that returned to in-progress, total the AI consumption costs associated with their attempts, and examine why they came back. Compare that with the cost of tasks completed without a restart.
Note: Our report did not include token consumption data, so the 66.7% increase cannot be converted into a measured dollar loss. It identifies where duplicated spend may be accumulating and what organizations should instrument to find out.
How to reduce work restarts
The first step is to learn where tasks return from and why. A task rejected in review for violating an architectural convention calls for a different fix from one returned by QA because it fails an acceptance test. Track restart reasons alongside the stage the task reached, then look for patterns.
Next, improve the context available before authoring begins. An agent can read the current codebase and still miss the history behind a design choice, a security constraint, or a testing requirement. Providing that knowledge up front gives the first attempt a better chance of surviving review and QA. In practice, that means maintained rules files such as AGENTS.md or skills, task descriptions with explicit acceptance criteria, and a plan the developer approves before the agent writes code. Repeated restart reasons can reveal which information is missing.
Teams should also move checks earlier when the requirements can be stated clearly. If QA repeatedly catches the same failure, add an appropriate test or acceptance criterion. If reviewers repeatedly explain the same convention, capture it in guidance available to future work. Make those checks part of the agent's definition of done, so it iterates against tests, linting, and coverage gates before the PR opens. Human review comments are especially useful when they reveal organizational knowledge that was never written down for the agent.
Finally, keep each change small enough to verify. A bounded task gives developers and agents a clearer target and makes a wrong turn easier to spot before a large change moves downstream.
Watch restart rate together with time in QA, repeat review issues, rework churn, and AI spend per completed task. Split each by PR origin (human-authored, AI-assisted, agent-authored) so you can see where the returns come from. If those measures improve, the team has stronger evidence that better authoring context is reducing duplicated work.
Better context, fewer restarts
Some tasks will always need revision. The goal is to prevent the same missing context or misunderstood requirement from sending work back to be restarted again and again. As AI accelerates code creation and agents take on more tasks across the SDLC, getting the first attempt onto the right path decides whether the speed is kept or paid back.
{{cta}}